
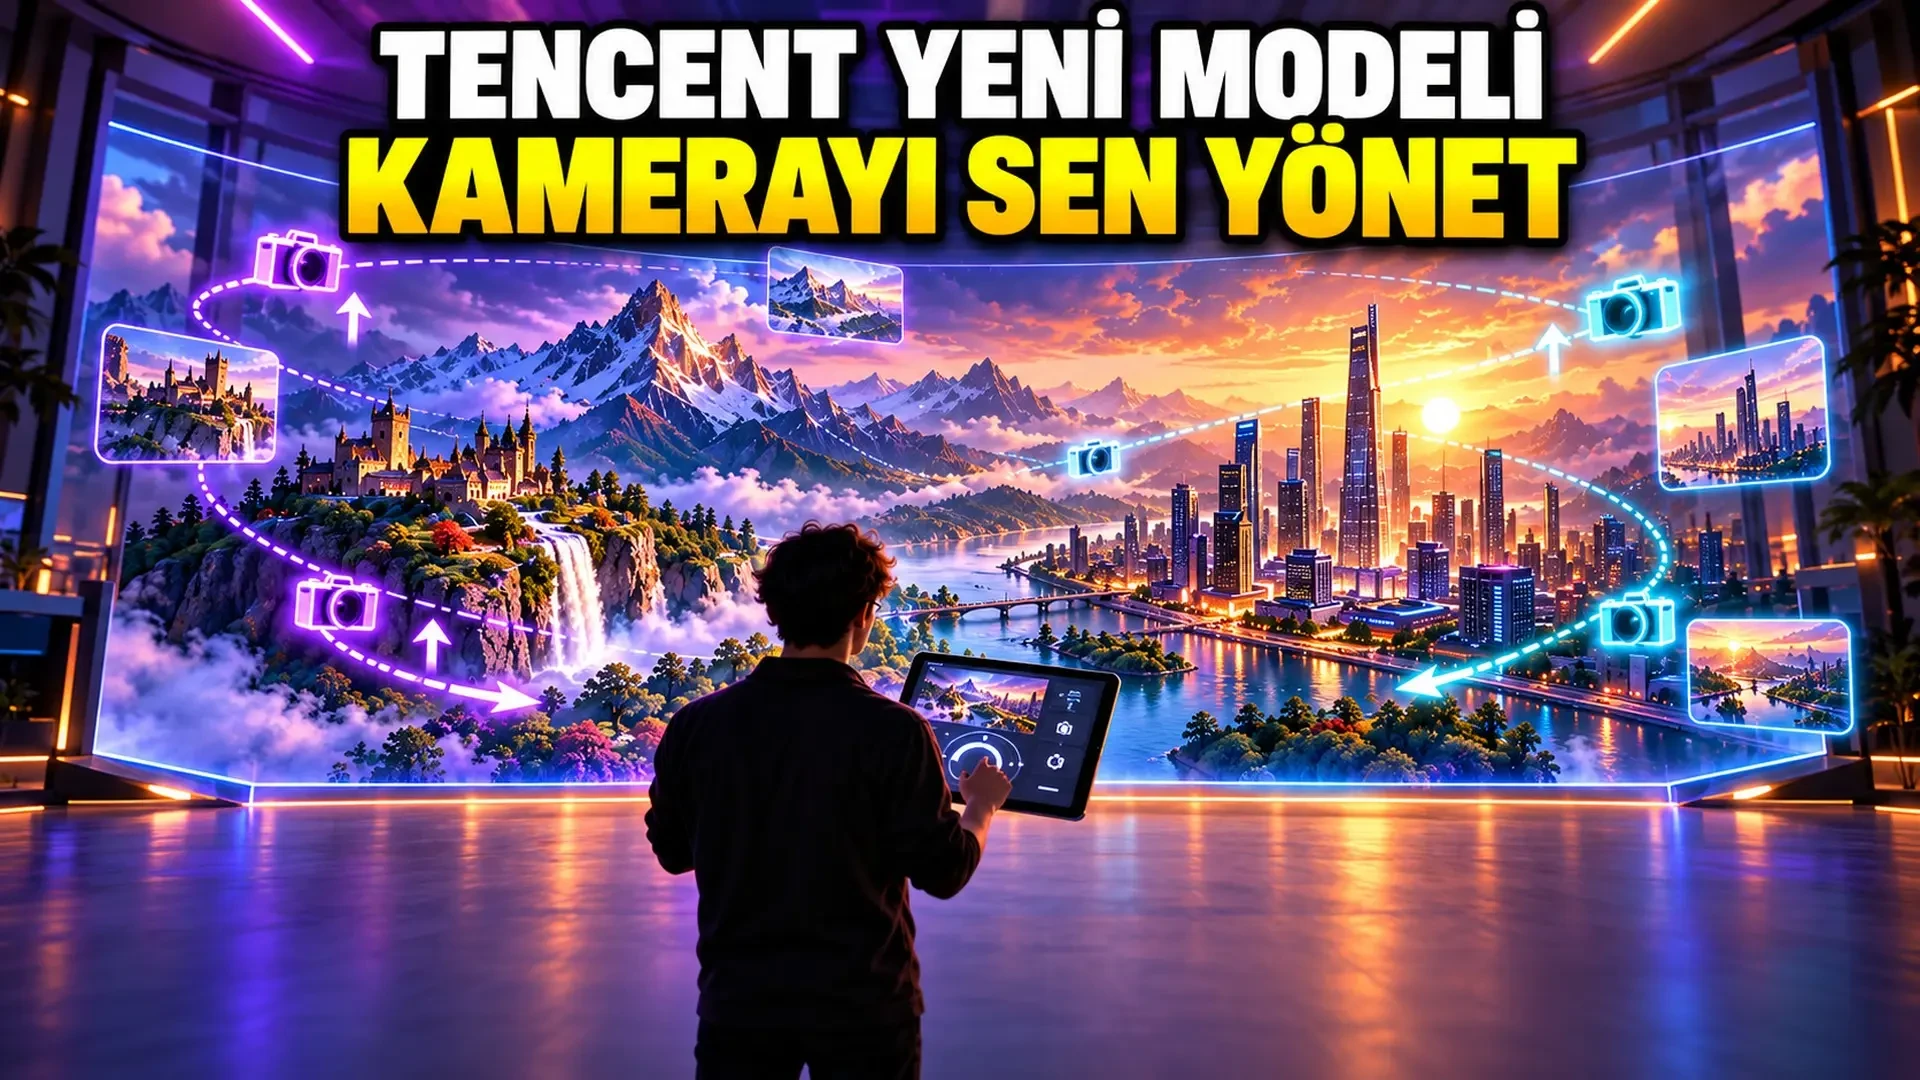
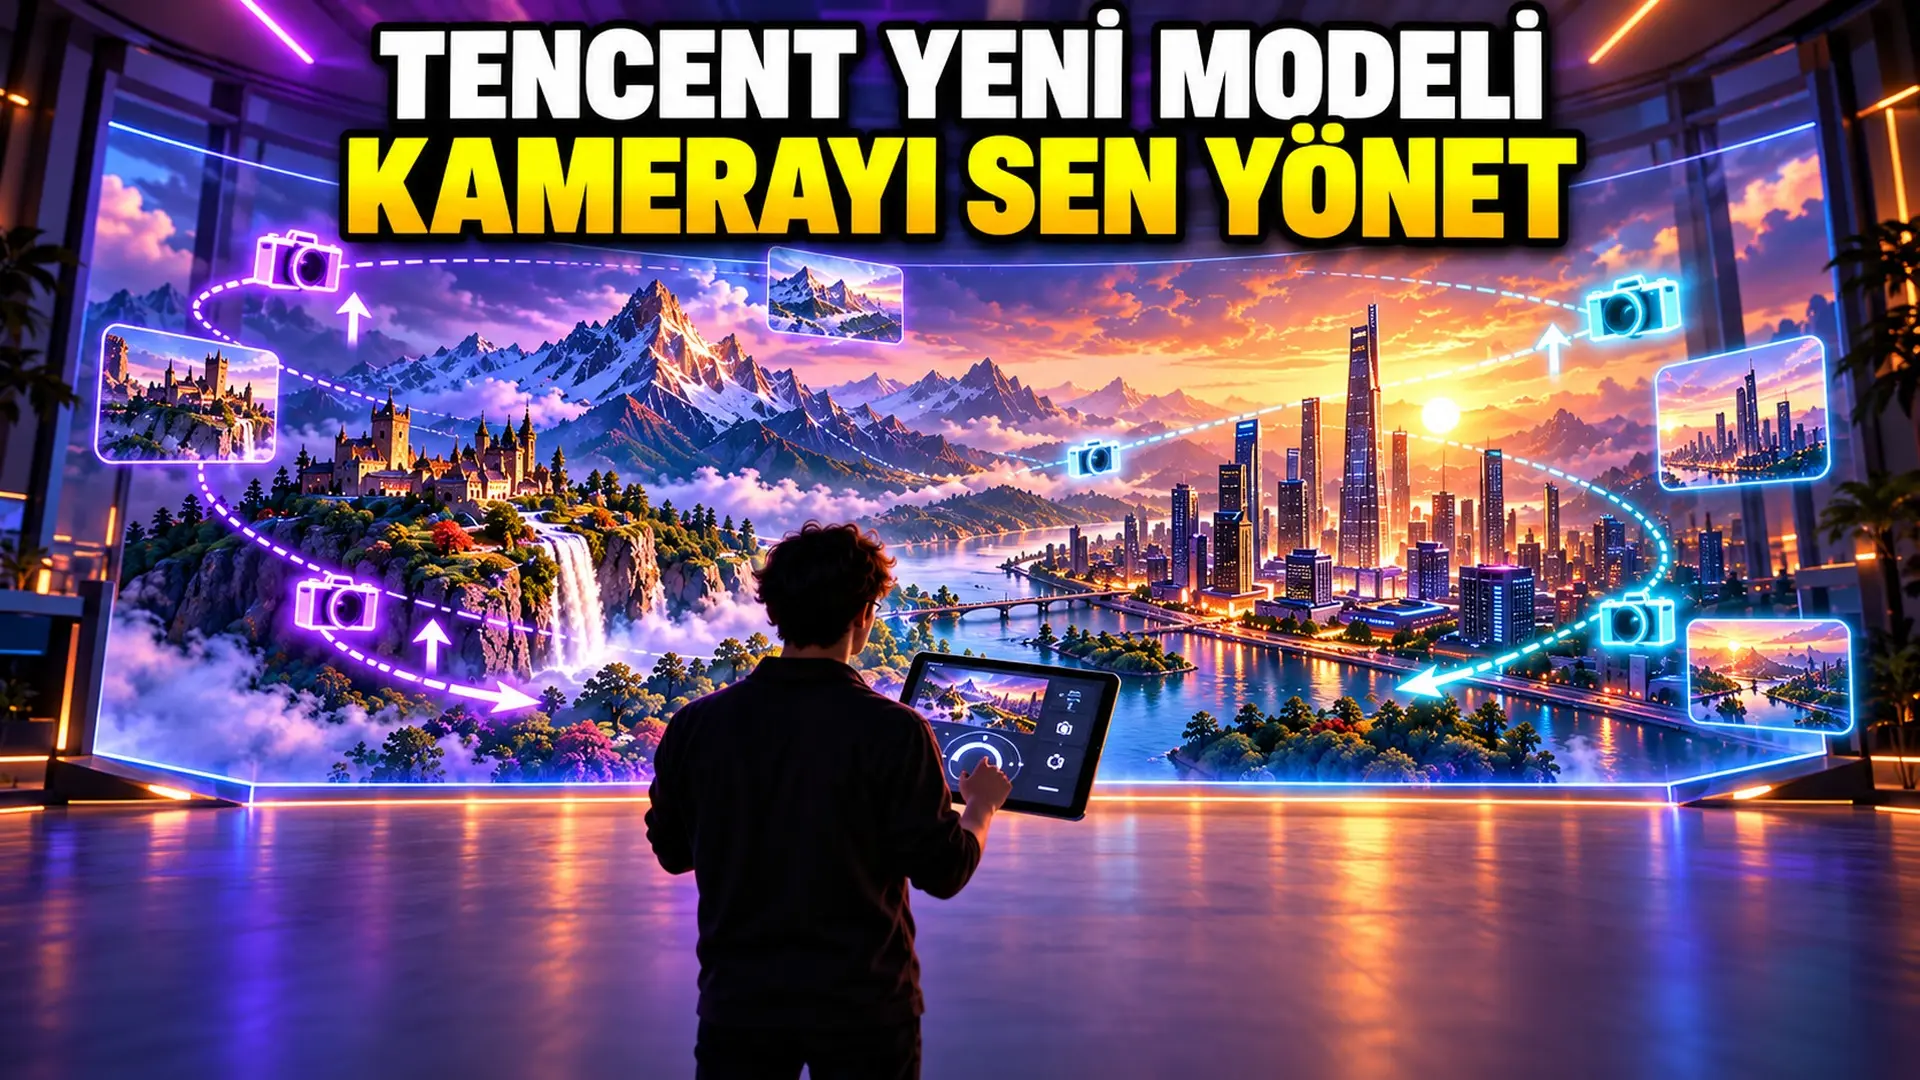
Tencent’s artificial intelligence research division, Hunyuan, has officially released Hy-Nomas, an open-source video world model engineered to transform how generative video content is created and manipulated. Unlike traditional text-to-video generation architectures that synthesize short, static video clips in a single non-interactive pass, Hy-Nomas operates as a free-form interactive world model. It constructs video sequences incrementally—piece by piece—allowing users to inject new textual instructions and precise camera trajectory commands at every stage of the generation process.
By releasing the model weights and source code under the permissive Apache 2.0 license, Tencent has opened access to advanced interactive video synthesis for both independent researchers and commercial developers. The model has been published across public repositories, including GitHub and Hugging Face, accompanied by hardware optimization configurations that enable it to run locally on a single consumer-grade graphics card, such as the NVIDIA GeForce RTX 4090.
The release represents a significant shift toward controllable, long-horizon video generation. By combining multi-step user steering, cached temporal memory, and lightweight domain adaptation, Hy-Nomas bridges the gap between static media generation and dynamic visual world simulation.
Generating Worlds Piece by Piece Through Interactive Control
According to technical specifications published on the model’s official Hugging Face repository, Hy-Nomas is designed around the concept of free-form, multi-step user interaction. Conventional generative video systems typically accept a single input prompt and generate a video clip of predetermined length, leaving users with little to no agency over how scenes unfold over time. In contrast, Hy-Nomas divides the rendering workflow into sequential video segments, creating an interactive feedback loop between the user and the system.
During the generation process, users can modify the scene dynamically at each step. This interactive framework supports a wide array of fine-grained controls:
- Creators can introduce new objects or entities into an ongoing visual stream.
- The overall visual style, lighting, or environmental setting can be transformed mid-sequence.
- Specific trajectories and physical actions for characters within the frame can be updated on the fly.
- Explicit camera movements can be commanded, granting full directional control over perspective and framing.
To maintain visual and logical consistency across extended video sequences, Hy-Nomas implements a specialized "world memory" architecture. Information from previously generated video segments is preserved within a dedicated context cache. As new prompts or camera instructions are introduced, the model queries this memory cache to ensure that spatial layouts, background environments, lighting setups, and object persistent details remain stable. This persistent context management allows the model to support long-horizon generation, preventing the visual drift, sudden scene teleports, and contextual contradictions that frequently degrade long video outputs in traditional generative architectures.
By maintaining state awareness across multiple generation steps, Hy-Nomas functions less like an automated video renderer and more like an interactive digital simulation environment. Users can navigate through generated space, alter storylines dynamically, and re-frame continuous shots without breaking the physical or visual realism established in earlier frames.
Hardware Optimization and Technical Architecture
Beyond its interactive generation capabilities, Hy-Nomas addresses one of the primary hurdles facing modern generative video models: high compute requirements. Video world models typically demand massive clusters of high-bandwidth enterprise GPUs to process multi-frame context and high-resolution diffusion steps. However, Tencent’s engineering team designed Hy-Nomas with lightweight architectural optimizations aimed at broadening deployment accessibility.
The system relies on a modular pipeline composed of several specialized neural network components:
- Text Encoding: The model integrates Qwen, an advanced open-weights language model, to process complex, multi-layered natural language prompts and translate human instructions into deep semantic representations.
- Camera Conditioning: Specialized camera conditioning modules parse direct camera trajectory coordinates, aligning visual synthesis with explicit mathematical camera movements such as pans, tilts, zooms, and complex orbital shots.
- Video Decoding: The primary visual reconstruction is handled by the PixelUMM video decoder, which synthesizes latent state representations into high-fidelity video frames.
To ensure computational efficiency during interactive sessions, Tencent introduced an accelerated inference pipeline. This optimized configuration utilizes an 8-step sampling process for each video segment. In this high-speed mode, Hy-Nomas outputs video clips at a resolution of 720 x 1280 pixels running at 24 frames per second (fps), striking a balance between rendering speed and visual clarity.
For local deployment on consumer hardware, Tencent provided a specialized deployment configuration tailored for single-GPU setups, specifically targeting cards like the NVIDIA GeForce RTX 4090 equipped with 24GB of VRAM. Operating complex video world models on single consumer GPUs typically leads to severe memory bottlenecks. To overcome this limitation, Hy-Nomas employs multi-level quantization techniques, utilizing low-precision numerical formats including INT8 and FP8. These compression methods significantly reduce the model’s memory footprint and bandwidth requirements without sacrificing model performance or fidelity.
Furthermore, the single-GPU execution framework leverages CPU memory offloading strategies. Non-critical model weights, state caches, and intermediate tensor data are systematically offloaded to system RAM and transferred to GPU VRAM only when required for computation. This hybrid memory management strategy ensures that memory-intensive processes remain within the hardware limitations of single-card workstations, allowing developers, animators, and AI enthusiasts to run and fine-tune interactive video generation setups locally.
Open-Source Ecosystem, Benchmarking, and Specialized Applications
Tencent’s choice to release Hy-Nomas under the open-source Apache 2.0 license facilitates widespread adoption across both academic research and commercial software development. The source code, operational dependencies, and pre-trained model weights have been made publicly accessible via GitHub and Hugging Face, enabling the global AI community to inspect, modify, and build derivative models upon the core architecture.
A notable feature of the Hy-Nomas framework is its support for Parameter-Efficient Fine-Tuning via Low-Rank Adaptation (LoRA). Lightweight LoRA modules allow developers to adapt the base world model to highly specialized domains without requiring full retraining of the underlying network parameters. Tencent explicitly highlights robotics as a primary domain for such domain-specific adaptations. In robotic systems, world models serve as predictive simulators, allowing autonomous agents to visualize physical spatial changes, anticipate environmental transformations, and simulate movement trajectories prior to real-world execution.
To support standardized evaluation of interactive video models across the broader industry, Tencent also developed and released a comprehensive evaluation dataset named Hy-Nomas-Bench. Designed to measure interaction control precision, the benchmark suite consists of:
- 280 Test Scenarios: Standardized prompts designed to test specific interaction capabilities, including text-driven scene modifications, environmental shifts, and entity management.
- 220 Reference Camera Trajectories: Preset camera motion paths used to evaluate how accurately the model follows explicit directional and spatial movement commands.
Hy-Nomas-Bench evaluates systems across three distinct operational modes: text-only instruction adherence, camera trajectory tracking accuracy, and hybrid control, where simultaneous text commands and camera trajectories are executed concurrently. The dataset includes benchmark video outputs alongside quantitative scoring tables, establishing a standardized baseline for comparing interaction fidelity, visual persistence, and control responsiveness in interactive world models.
By releasing the model weights, hardware optimization pathways, and standardized evaluation tools simultaneously, Tencent’s Hunyuan team has established a comprehensive open-source framework for controllable, multi-step video synthesis. The release opens new pathways for creative tool development, synthetic data generation, spatial simulation, and robotics research across the machine learning community.